Blog

  • From AI Adoption to AI Acceleration: What We’re Hearing on the Ground

    From AI Adoption to AI Acceleration: What We’re Hearing on the Ground

    In the past few months, something interesting has started happening in almost every conversation we’re having with enterprise leaders.

    The language has shifted.

    • From “Should we explore AI?” To “How fast can we scale it?”
    • And that single shift — from curiosity to conviction — changes everything.

    The AI Journey is Real, But It’s Not Linear

    Most enterprises we speak with are not starting from scratch. They’ve run pilots, tried a few PoCs, maybe even launched a use case or two in production.

    But here’s where it gets tricky: scaling that first success.

    It’s not that they lack intent. Or even ideas.

    It’s that every new use case starts to feel like reinventing the wheel:

    • New teams
    • New data pipelines
    • New infra challenges
    • New integration headaches

    That’s not scale — that’s repeat chaos.

    How do we make this “our AI journey” — not just another tech implementation?


    What’s Becoming Clear: Platform + Services is the Winning Formula

    If you’re in the trenches of AI adoption, you know this already: No single product will solve your problems. And no amount of consulting alone will make AI adoption sustainable.

    It has to be both:

    • A platform that gives you a repeatable foundation
    • Services that make that foundation real, contextual, and outcome-oriented

    This is not theory — this is the real-world formula that’s working.

    The smart enterprises aren’t just choosing tools.

    They’re choosing platforms that align with their business.

    And service teams that understand the domain, not just the tech.


    What Enterprises Are Telling Us They Want

     Whether it’s insurance, banking, logistics, or retail — the themes are consistent:

    – A way to move from one use case to many, without rework

    – Clear cost-benefit alignment from Day 1

    – No lock-ins — especially when it comes to data and models

    – Full transparency and control on how their AI is built and run

    • A partner that helps, not takes over

    – And above all, speed that doesn’t come at the cost of stability.


    Final Thought: AI Is No Longer “Next”

    We’ve crossed that phase.

    Now it’s about how fast, how sustainably, and how confidently you can scale it.

    Some will still stay stuck in experimentation.

    Others are already laying down their foundations to make AI an engine — not an experiment.

    If you’re in the second group, the real questions aren’t about whether AI works.

    They’re about how to make it work for your enterprise, your team, and your stack.

  • From Whispers of “Should We?” to a Roar of “How Fast?”: The AI Acceleration Imperative

    From Whispers of “Should We?” to a Roar of “How Fast?”: The AI Acceleration Imperative

    The air in enterprise leadership conversations has palpably shifted. The hesitant inquiries of “Should we explore AI?” have been decisively replaced by a resounding “How fast can we scale it?”. This single pivot, from mere curiosity to unwavering conviction, fundamentally alters the AI landscape.

    The AI journey, while undeniably real, is far from a linear ascent. Most organizations don’t start from a blank slate. They’ve dipped their toes in the water with pilots, navigated a few proofs of concept, and perhaps even launched a solitary use case into the live environment. But the crucial bottleneck emerges when attempting to replicate that initial success.

    It’s not a lack of ambition or even a shortage of innovative ideas that hinders progress. Instead, each new AI initiative feels like a Sisyphean task of reinvention: assembling fresh teams, constructing bespoke data pipelines, wrestling with novel infrastructure complexities, and untangling yet another web of integration challenges. This isn’t scalable growth; it’s a cycle of repetitive chaos.

    The dominant question echoing across boardrooms now is: “How do we inject predictability into this process?”

    The most critical and honest inquiries revolve around:

    • Building on Solid Ground: How do we prevent our AI initiatives from being built on shifting sands of uncertainty?
    • Exponential Velocity: How do we ensure that each subsequent use case is deployed with greater speed and efficiency than the last?
    • Trustworthy AI: How do we guarantee that our deployed models are rigorously governed, fully auditable, and inherently safe?
    • Unified Scalability: How do we architect a system that allows us to build once and then scale our AI capabilities with unwavering clarity?
    • Our Unique AI Identity: And, most importantly, how do we forge our distinct AI journey, rather than merely implementing another generic technology?

    The Unambiguous Answer: Platform + Services = Sustainable AI Power

    For those navigating the complexities of AI adoption, this truth has become self-evident:

    No standalone product can magically solve your AI challenges.

    And no amount of abstract consulting can, on its own, forge a sustainable AI future.

    The winning formula is a powerful synergy: 

    • A Robust Platform: Providing a repeatable and standardized foundation for all AI initiatives.
    • Strategic Services: Grounding that foundation in your specific context, driving tangible outcomes, and making the abstract real.

    This isn’t theoretical conjecture; it’s the proven equation driving success in the real world. Forward-thinking enterprises aren’t just selecting disparate tools; they are strategically choosing platforms that deeply align with their core business objectives. They are also partnering with service teams that possess a profound understanding of their industry, not just the underlying technology.

    The Unified Enterprise Demand: Clarity, Control, and Velocity

    Across diverse sectors – be it insurance, banking, logistics, or retail – a consistent set of demands is emerging:

    • Effortless Scalability: A clear pathway to move from isolated successes to widespread AI deployment without constant reinvention.
    • Tangible ROI: Clear and demonstrable cost-benefit alignment from the very outset of any AI project.
    • Freedom and Flexibility: No vendor lock-in, particularly concerning the crucial assets of data and AI models.
    • Unwavering Transparency and Control: Complete visibility and authority over how their AI is architected, built, and operated.
    • Strategic Partnership: A collaborator who empowers and guides, rather than dictates or takes over.
    • Sustainable Speed: The ability to accelerate AI initiatives without compromising stability or introducing undue risk.

    The Decisive Turning Point: AI Is Now

    The era of “next generation” AI is over. We have decisively crossed that threshold.

    The critical question now isn’t if AI works, but how swiftly, how sustainably, and how confidently you can scale its transformative power within your organization.

    Some will inevitably remain mired in perpetual experimentation. Others are already strategically laying the groundwork to transform AI from a series of isolated projects into a powerful, integrated engine of growth and innovation.

    If you belong to the latter group, your focus has rightly shifted. The fundamental questions about AI’s potential have been answered. Now, the vital inquiries center on how to tailor AI to the unique contours of your enterprise, empower your teams, and seamlessly integrate it into your existing technology stack.

    That’s the crucial conversation we’re here to facilitate.

    #DSWUnifyAI #DSWAIHub #EnterpriseAI #GenAI #AIAdoption #AIinBusiness #AITransformation #ResponsibleAI #AppliedAI #AIAcceleration #GoToProduction #AIatScale #AIDelivery #PlatformThinking

  • Disruption Is Constant — But Enterprise AI Demands Stability, Speed, and Scalability

    Disruption Is Constant — But Enterprise AI Demands Stability, Speed, and Scalability

    We’re living through a wave of AI innovation unlike anything before. Each week seems to bring a new generative AI (GenAI) model, a smarter agent, or a groundbreaking open-source tool. Disruption is no longer rare — it’s routine. 

    But inside the enterprise, the excitement of innovation meets the complexity of real-world execution. 


    Innovation Is Everywhere — Adoption Is the Challenge 

    It’s not that enterprises lack ambition or ideas. The real challenge is how to integrate, govern, and scale these innovations sustainably. 

    Enterprises aren’t just testing what AI can do anymore. They’re asking: 

    • How do we move AI use cases into production faster?
    • How can we scale from one use case to many — without starting over each time? 
    • How do we ensure trust, compliance, and control? 
    • How do we avoid building a patchwork of disconnected tools?

    The conversation is evolving from tools to systems of execution — where AI adoption becomes repeatable, manageable, and results-driven. 


    The Rise of the AI Platform Mindset 

    AI is no longer just another IT project. It’s becoming a strategic layer in how decisions are made, how customer experiences are designed, and how services are delivered. 

    That shift requires more than just toolkits or APIs. It demands enterprise AI platforms that are:

    • Modular and reusable
    • Governable within enterprise policies 
    • Integration-friendly with legacy environments
    • Open and composable for future innovation 

    Platforms win not just on features — but on alignment: across teams, tools, and outcomes. 


    From First Use Case to Fast-Track Execution 

    Despite AI’s promise, many organizations face a familiar roadblock: 
    The first use case takes months. The second one? Often feels like square one. 

    Governance hurdles, IT reviews, and siloed infrastructure can bring GenAI initiatives to a crawl.

    But when the right AI platform is in place: 

    • AI/ML use cases can reach production in weeks
    • GenAI copilots move from prototype to deployment in hours
    • Models, pipelines, and governance frameworks become reusable
    • Each iteration becomes faster, more cost-effective, and more scalable

    Speed is important — but scalability is everything. 

    The New Role of Services in Enterprise AI

    As platforms take center stage, services are transforming too. 

    It’s no longer just about building one-off AI solutions. It’s about: 

    • Orchestrating AI across business functions
    • Embedding it into enterprise systems 
    • Aligning everything from data architecture to regulatory compliance

    The future lies in a platform + services model — where enterprises gain technical capability and strategic alignment. One fuels the other. 


    What Enterprise Leaders Want From AI 

    As AI becomes a core part of digital transformation, leaders are aligning around five priorities:

    1. Faster time to production
    2. Repeatable, scalable AI deployment
    3. Built-in governance and compliance
    4. Modular, reusable components
    5. Ability to adopt new innovations — without chaos

    The goal is clear: AI that’s theirs, not another vendor’s roadmap.


    From Pilots to Systems of Execution 

    The enterprises gaining the most from AI aren’t the ones running dozens of pilots. 

    They’re the ones building systems of execution:

    • Where AI is part of the operating model
    • Where each success accelerates the next
    • Where innovation and governance co-exist
    • Where disruption is operationalized, not just admired

    Because in enterprise AI, production isn’t the end — it’s the beginning.  

    Final Word: It’s Not About What’s Next — It’s About What’s Repeatable 

    New GenAI models will keep coming. 
    New frameworks will trend.

    But success in enterprise AI won’t be about chasing what’s next — it’ll be about operationalizing what works.

    The enterprises that lead won’t be those who rode every wave. 
    They’ll be the ones who built the architecture to ride any wave — with trust, speed, and control.  

  • The Future of Enterprise AI: Why Platforms Will Define the Next Wave of AI Adoption

    The Future of Enterprise AI: Why Platforms Will Define the Next Wave of AI Adoption

    AI is at an inflection point. As enterprises move from pilot experiments to large-scale deployments, one thing is clear: the way AI is built, deployed, and operationalized needs a fundamental shift.

    Open-source AI has been the backbone of AI innovation—powering everything from foundational models to domain-specific advancements. It has enabled rapid experimentation and research, allowing businesses to explore AI without constraints. However, now as AI adoption needs to accelerates from experimentation to production, enterprises require a structured, scalable, and predictable approach to execution.


    AI Adoption Is Growing, But the Path to Production and Scale Is Still Complex

    Organizations are not struggling with AI innovation; they are struggling with AI execution. The challenge is not just building AI models but ensuring they integrate seamlessly into business processes, deliver measurable impact, and remain cost-effective at scale.

    Key hurdles enterprises face in AI adoption include:

    • Fragmentation of AI solutions – Different teams use different AI stacks, leading to inefficiencies in scaling.
    • Unpredictability in AI outcomes – AI models need continuous adaptation to remain accurate and effective.
    • Governance, compliance, and explainability – Regulated industries need full traceability of AI decisions.
    • Infrastructure complexity – AI workloads require flexible deployment across cloud, on-prem, and hybrid environments.

    As AI moves from experimentation to large-scale business transformation, enterprises require a unified approach to orchestrate, manage, and scale AI workloads efficiently.


    The Shift Towards Enterprise AI Platforms

    Over the past decade, enterprise software has evolved from fragmented, best-of-breed tools to platform-based solutions. AI is following the same trajectory.

    AI in enterprises cannot remain a collection of disjointed models and tools—it needs to function as a cohesive, scalable system that integrates with existing infrastructure, data ecosystems, and governance frameworks.

    A robust AI platform should:

    • Enable end-to-end AI execution – From data ingestion to model deployment and continuous learning.
    • Standardize AI workflows – Ensuring repeatability, governance, and scalability.
    • Support hybrid & multi-cloud deployment – Giving enterprises full flexibility over where AI runs.
    • Provide explainability & compliance – Making AI decisions transparent and auditable.
    • Eliminate vendor lock-in – Allowing enterprises to control their AI roadmap, infrastructure, and costs.

    Why Enterprises Need AI Platforms Now

    Organizations are leveraging AI for process automation, predictive analytics, customer intelligence, risk management, and decision optimization. However, many AI initiatives remain fragmented and fail to scale across business functions.

    For AI to drive true transformation, it must:

    • Be production-ready from day one – AI models should integrate directly into business workflows without long development cycles.
    • Enable dynamic decision-making – AI should adapt to real-time user interactions, operational changes, and risk evaluations.
    • Ensure compliance and governance – AI-powered decisions must be fully auditable and explainable.
    • Scale across multiple AI/ML and GenAI use cases – A platform approach ensures seamless execution across different AI-driven processes.

    Building an AI Platform for the Future

    The synergy between open-source AI and enterprise AI platforms is redefining how businesses adopt and scale AI. Open-source AI fosters innovation, but enterprises need structured execution frameworks to make AI predictable, secure, and production-ready.

    The future of AI adoption will be shaped by platforms that:

    • Leverage open-source AI with enterprise-grade reliability – Bringing the best of open frameworks into a structured, scalable system.
    • Enable end-to-end AI lifecycle management – From data processing to AI model execution and monitoring.
    • Adopt a GenAI-first approach with explainability and governance – Ensuring AI decisions are transparent, auditable, and compliant.
    • Operate in a no vendor-lock environment – Giving enterprises the flexibility to build AI on their own terms.

    Breaking the Barriers to Enterprise AI Adoption

    AI has immense potential, but its true impact is realized when it moves from isolated experiments to real-world execution at scale. Enterprises do not need more AI tools—they need a structured, predictable way to adopt AI across their business.

    As AI adoption accelerates, enterprises must move beyond fragmented solutions and embrace platform-driven approaches that provide scale, security, and governance. AI will not be defined by isolated models but by how businesses execute AI at scale with confidence, control, and transparency.

    For enterprises looking to scale AI with predictability and impact, the conversation is shifting—from experimenting with AI to executing AI with structure, efficiency, and real-world value.

  • Getting started with machine learning algorithms: Linear Regression

    Getting started with machine learning algorithms: Linear Regression

    In supervised machine learning, there is a plethora of machine learning models like linear regression, logistic regression, decision tree and others. we use these models to resolve classification or regression problems, and ensemble learning is a part of supervised learning that gives us models that are built using several base models. Random forest is one of those ensemble learning models that are popular in the data science field for its high performance.

    Technically, random forest models are built on top of decision trees and we have already covered the basics of a decision tree in one of our articles, so we recommend reading the article once to understand this article’s topic clearly. In this article, we will talk about random forests using the following points.

    Table of content

    • What is Random Forest?
    • How Does a Random Forest Work?
    • Important Features
    • Important Hyperparameters
    • Code Example
    • Pros and Cons of Random Forest

    What is Random Forest?

    Random forest is a supervised machine-learning algorithm that comes under the ensemble learning technique. In supervised machine learning, a random forest can be used to resolve both classification and regression problems.

    As discussed above that, it comes under the ensemble learning technique, so it works on top of many decision trees. We can say that decision trees are the base model of a random forest. The algorithm simply builds many decision trees on different data samples, and using the majority vote system solves the classification problem. In the case of regression, it uses the average of the decision trees.


    How does a Random Forest Work?

    When we talk about the working of the random forest, we can say that it gives outcomes by ensembling the results of many decision trees. Here if we talk about a classification problem, each decision tree predicts an outcome and whatever the class gets majority votes comes out as the final result of a random forest. Let’s take a look at the below image.

    random-forest

    When we talk about the working of the random forest, we can say that it gives outcomes by ensembling the results of many decision trees. Here if we talk about a classification problem, each decision tree predicts an outcome and whatever the class gets majority votes comes out as the final result of a random forest. Let’s take a look at the below image.

    The above image also gives the intuition behind the ensemble learning technique, where the final prediction is made by combining the results of several other models. The ensemble learning technique can be followed using two ways:

    1. Bagging: this way, we divide data into various subsets and train the base models like decision trees in a random forest, and the majority vote for any class comes out as the final result.
    2. Boosting: this way, we combine weak learners with strong learners and make a sequence of the model so that the final model is most accurate amongst every learner. For example, XG boost and ADA Boost models.
    random-forest-2

    Random forest in ensemble learning uses the bagging method. We can say that every decision tree under the random forest uses a few samples from the whole training data to get trained and give predictions. Let’s talk about the steps involved in training the random forest algorithm.

    Steps involved

    1. First, it extracts n number of subsets from the dataset with k number of data points that we call n subsets.
    2. n number of decision trees are constructed to get trained using n subsets.
    3. Each decision tree gives predictions.
    4. Final predictions are generated using the majority voting system for the classification problem and an averaging system for the regression problem.

    Using the above four steps working of a random forest gets completed. Next, let’s discuss the important features of a random forest.

    Important features

    1. Highly immune to dimensionality: Since all data features are not considered in the making of decision trees, the whole random forest gives high performance even in a situation where data is high-dimensional.
    2. Diversity: every decision tree uses some of the features from the data. That’s why the training procedure becomes different for the different decision trees. At final, we get more optimum results.
    3. Data split: while making a random forest, we don’t really need to spit data in train and test because there will always be some percentage of data unknown for a decision tree.
    4. Stable: random forests are stable algorithms when modelled because the majority voting or averaging system is used to make the final prediction.
    5. Parallelization: as we know, every individual decision tree uses a part of the main data. It makes full use of the CPU to train random forests.
    6. No overfitting: as the final results from the random forest come from the majority voting or averaging system and the decision tree uses subsets to get trained, there are fewer chances of overfitting.

    Important Hyperparameters

    In the above we have discussed the working and features of random forests, here we will discuss the important hyperparameters of any random forest using which we can control the random forest while increasing its performance and making it’s working or calculation faster.

    1. n_estimators- The number of decision trees required to build the random forest.
    2. max_features- Maximum number of features that random forest will use from data to split the data.
    3. mini_sample_leaf — minimum number of leaves is required to split the decision tree node.
    4. n_jobs — we use it to speed up the calculation of random forest because it tells the number of processors a system needs to train the model.
    5. random_state- just like for other models, it controls the randomness of the sample.

    Code Example

    In the above discussion, we have seen how random forest work and their important hyperparameters. Now after knowing this, we need to know how it works using any tool. So here we will look at the simple implementation of the random forest using the python programming language.

    We will use randomly generated data and the sklearn library in this implementation. So let’s start with generating data.

    from sklearn.datasets import make_classification
    X,y = make_classification(n_samples = 2000, n_features = 6, n_informative = 3)
    print(‘data features n’,X)
    print(‘data_classes n’, y)

    Output:

    random-forest-3

    Here we can see features and classes of randomly generated data. In the making of data, we have generated 2000 samples that have 6 features and one target variable.

    Let’s build a model

    from sklearn.ensemble import RandomForestClassifier
    clf = RandomForestClassifier(max_depth = 4, random_state = 42)

    Here we have created an object named clf that consists of a random forest classifier. Let’s train the model.

    clf.fit(X,y)
    print(‘count of the decision trees :’,len(clf.estimators_

    Output:

    random-forest-4

    Here we can see that 100 decision trees are under the random forest. Now we can draw a decision tree from our random forest using the following lines of code:

    import matplotlib.pyplot as plt

    from sklearn import tree

    plt.figure(figsize=(12, 10

    tree.plot_tree(clf.estimators_[0],max_depth = 2)

    plt.show()

    Output:

    random-forest-5

    Here we have implemented a random forest, and to increase the explainability, Now we can draw a decision tree from a random forest using the following lines of code:

    print(clf.predict([[0, 0, 0, 0, 0, 0]]

    print(clf.predict([[1, 0, 1, 0, 1, 1]]


    Output:

    random-forest-6

    Now results from the model are in front of us and this is how we can implement a basic random forest. Let’s take a look at the pros and cons of the random forest algorithm.

    Pros and Cons of Random Forest

    Pros

    1. We can use it for both classification and regression problems.
    2. It does not overfit.
    3. It can also work with data that contains null values.
    4. High-performing with high dimensional data.
    5. It maintains diversity in the results.
    6. Highly stable.

    Cons

    1. Random forest is a highly complex algorithm.
    2. Training time is more because it takes more time to calculate, develop and train decision trees.

    Final words

    Under the series of articles, this article consisted the information about the random forest, which is a machine learning algorithm used to resolve problems that come under supervised learning. In the article, we have discussed the what, why and how of random forests. Using an example we looked at its implementation. Looking at the pros and cons of this model, we can say that it has such features and functionality that gives us higher accuracy. Still, before using this model we should understand the basic concept behind the model so that we can tune it appropriately.


    About DSW

    Data Science Wizards (DSW) is an Artificial Intelligence and Data Science start-up that primarily offers platforms, solutions, and services for making use of data as a strategy through AI and data analytics solutions and consulting services to help enterprises in data-driven decisions.

    DSW’s flagship platform UnifyAI is an end-to-end AI-enabled platform for enterprise customers to build, deploy, manage, and publish their AI models. UnifyAI helps you to build your business use case by leveraging AI capabilities and improving analytics outcomes.

    Connect us at contact@datasciencewizards.ai and visit us at www.datasciencewizards.ai

  • Introduction to Data Orchestration

    Introduction to Data Orchestration

    According to a report by Gartner, more than 87% of organisations are not capable of utilising data for business intelligence and data analytics. The one reason behind this can be the inability to extract the right data from the data silos. Since these silos are data tables and restricts data to be migrated to other locations, data migration becomes a really complex task.

    Also, the organisations have many more operations to handle, they lack in data governance. There can be various scenarios which restrict companies or organisations to extract and analyse their data. Data orchestration is one of the solutions that helps in the process of taking siloed data out from multiple data storages or data locations, combining and organising it, and automating data flow to data analysis tools. In this article, we will have an introduction to data orchestration. The points to be discussed in the article are listed below.


    Table of content

    • What is data orchestration?
    • Need for data orchestration
    • Parts of data orchestration
    • Challenges being overcome by data orchestration
    • Benefits of data orchestration

    What is Data Orchestration?

    Data orchestration is a process of automating data flow right from bringing all the data together to preparing and making it available for data analysis. In a primary term, we can say that data orchestration is a process of breaking down the high data storage in managed ways. The main motive behind the data orchestration should be to automate and streamline data to enhance the company’s data-driven decision-making.

    Some software/platforms like Apache Airflow, Metaflow, K2view, and Prefect help execute data orchestration by connecting storage systems, and data analysis tools can easily access the data. However, these software or platforms are completely new technology and don’t act like a data storage system.

    Talking about the traditional ways, they may involve the following time-intensive steps of preparing data from big storage:

    1. Use custom scripts to extract data in CSV, Excel, JSON or database formats.
    2. Validation and cleaning of the data.
    3. Data conversion is required form.
    4. Load into the target destination.

    Data orchestration is a way to exclude these time-intensive processes from the path of data preparation.


    Need for Data Orchestration

    The above-given data processing steps may be exemplary when the number of data systems is low. Still, when it comes to big businesses with multiple data systems, data orchestration becomes ideal. Using this technology, we don’t need to combine multiple data systems together. Instead, data orchestration provides access to the required data in the required format and at the time necessary.

    Using data orchestration, data available across multiple data sources can be accessed easily and quickly. It is also better because we don’t require any central data storage to handle large amounts of data.

    We may think of data orchestration as ETL(extract, transform, load process) but ETL has a specific written script to follow and process the data. Data orchestration is more on automation of the steps of ETL. There are a few parts of data orchestration. Let’s take a look at them.


    Parts of Data Orchestration

    Data orchestration can be segregated into 4 parts:

    1. Preparation: This part includes the process of checking the integrity and correctness of data. Also labelling the data, providing designation to data and including third-party data with existing data can be completed in this part.
    2. Transformation: this part includes the data conversion and formatting. For example names of people can be written in different formats like [surname] [name] or [name] [surname]. So here, we are required to make all these in the same format.
    3. Cleaning: This part includes data cleaning processes, identification and correcting the corrupt, inaccurate, nan, duplicated and outlier data.
    4. Synchronising: This part includes continuous updations in the way of data from data source to destinations so that consistency can be maintained. This part is similar to your photos, videos and contacts synced on all your devices using google drive.

    Challenges being overcome by data orchestration

    Data orchestration came into the picture when handling big data became more complex. There are various challenges people are facing while handling big data using ETL. These challenges include:

    • Disparate data sources: In large organisations, when data comes from multiple data sources, it doesn’t come in the analysis-ready situation. Here, data orchestration plays an essential role by automating the data maintenance and quality checking process.
    • Data Silos: There are higher chances of getting required data siloed in such a location or organisation from where accessing data for the subsequent processes is complex. Here orchestration helps in breaking down the silos and makes data more accessible. This breakdown of silos is done with the help of DAG(direct acyclic graph) that represents the relationship between tasks and data systems.
    • Data validation: As data literate, we know that data cleaning and organising are time-consuming processes. Data orchestration helps avoid such time consumption when data is required for analysis.

    Benefits of Data Orchestration

    Data orchestration can provide the following benefits:

    • Scalability: Being a cost-effective way to automate data synchronisation across data silos, Data Orchestration helps organisations to scale data use.
    • Monitoring: Data orchestration enables alerts and monitoring systems within it and that helps data engineers to monitor data flow across the systems where ETL utilises complex scripting and disparate monitoring standards.
    • Data governance: Orchestration helps users monitor customer data because the data gets collected throughout a system. For example, handling data of different geographical regions with different privacy and security rules and regulation.
    • Real-Time information analysis: One of the major benefits of data orchestration is that it allows real-time data analysis. Also till now, it is the quickest way to extract and process data.

    Final words

    In this blog, we have seen how data orchestration is making data more useful in accurate, efficient and quick way. Because of data orchestration, it has become common to leave our data fragmented and in silos. Along with this we went through its parts and looked at how every part stands and works. Since this technology has come in boom around the year 2010, it is in a developing phase where we can observe changes frequently. It won’t be surprising for us to see ETL be replaced by data orchestration in future. So keeping track of the development of such technology becomes very necessary for those who are dependent on data.

  • How is Artificial Intelligence Advancing the Insurance domain?

    How is Artificial Intelligence Advancing the Insurance domain?

    We have already witnessed the application of artificial intelligence in every sector, whether the industry is BFSI, medical or agriculture. Talking about the insurance sector, artificial intelligence is deeply integrated into it. Most sensitive use cases in the insurance domain like claims, distribution, and underwriting can be resolved using AI systems. According to the FBI’s report, the insurance industry is filled with more than 7000 insurance companies, and the collection of this industry goes more than $1 trillion annually. These statistics tell how big this industry is and survival in this industry requires highly advanced and competitive behaviour from companies. Here AI comes into the picture and ensures the company is performing well in every aspect. In this article, we will look at the significant use-cases of AI in the insurance sector, and the major advancements that AI can provide in Insurance Domain to be discussed are listed below.


    Table of Content

    1. Faster Claims Processing
    2. Accelerated claim adjudication
    3. Document Digitization
    4. Accurate Underwriting Risk Management
    5. Insurance Fraud Detection and Prevention
    6. Customer Services

    Faster Claims Processing

    Artificial intelligence-enabled products are best known as an option for the human workforce where repetitive and attention-demanding tasks are required to be completed. Such products perform such tasks faster and efficiently and drive the best ROI.

    For example, manual claim processings are prone to inefficiencies and errors because of extensive paperwork and digitised processing. On the other hand, a trained AI model becomes efficient and prone to a lesser error rate. According to a report by McKinsey&co, it is found that manual claim management can increase the premium revenue by up to 50–60%.

    The significant changes in insurance companies are found in the year 2021 when they plan to achieve better operational efficiency using the technologies such as:

    • AI
    • RPA
    • IoT

    With the emergence of the above-given advanced technologies in the insurance sector, RPA and IoT have become two significant points for data collection. Telematics and computers enabled in a car, fitness trackers, and healthcare devices are IoT devices that help in the generation of comprehensive data of customers that makes decision-making easy.

    At the same time, AI comes into the picture, which is an advanced means to process extensive and comprehensive data. As the data volume increases, AI models’ capacity also increases and the chances of errors decreases.

    AI advances the claim settlement procedures by streamlining the processing of incoming data. Data processing in claim settlement can include scanning, interpretation and decision-making. AI models have proven themselves best in such workflow, and as the data volume increases, they also improve themselves without requiring explicit programming and human intervention.

    The intervention of AI can make claim processing advanced in the following use-cases:

    • Claim routing
    • Claim sorting
    • Fraudulent detection
    • Claim management audit

    Fukoku mutual life is leveraging the AI models for the claim processing. The AI-enabled application can access all customers’ medical files and mine information out of them to calculate optimised payouts. After this calculation, the human agents are required to provide approvals.


    Accelerated claim adjudication

    Claim adjudication is a process where insurance companies decide between yes or no, and how much a claim needs to be settled for any case. However, this all process goes through a cyclic plan whether the insurer or customer wants to execute the cycle faster.

    Using AI models, this planning and execution become easier and much faster than manual processing. Many AI models have already been developed, and many are in the development process to perform different inspection tasks. They can be used for car, property, and human inspections during medical claims.

    AI intervention in claim adjudication is a compulsion to perform such inspection quickly, accurately, and honestly. Hardware and models involved in AI systems work for data collection and verification so that process of evidence gathering and appraisal sessions can be completed much faster and safer.

    For example, an AI-enabled system can use a camera to take pictures of objects, and a computer vision model can optimise these pictures to assess damages more efficiently and provide an estimated repair cost. These models can be utilised with drones to perform building damage, crop damage and industrial equipment damage inspection.

    AI models just require data to inspect and analyse such things, which can be collected using equipment like cameras and IoT devices. After the models and systems are verified, reports can be sent to an engaged inspector.

    Auto-insurer Tokio Marine is a company that has deployed such systems for examining and appraising damaged vehicles. After verifying them with the AI model, they just collect images and process the settlement.


    Document Digitization

    This is not only a use case for the insurance domain but also for domains like banking, education and finance. This use case requires optical character recognising systems to extract information from documents and pictures. This extracted information then gets collected and optimised for decision-making.

    It is majorly found that insurers are collecting the data in the form of paper like paper-based form, printed documents, and ID cards. At the top levels, it becomes a prominent issue in the management of these papers. In this scenario, OCR can be the game changer and provide high operational efficiencies. Also, OCR can reduce efforts of re-typing information and human mistakes.

    This not only enhances the accuracy of work but also allows the human workforce to engage in productive tasks. Furthermore, the management issues with papers are resolved because OCR can extract information, and after translating them into digital form, it goes into the databases in a managed way.

    In one of our articles, we have seen that such processes enhance the new customer onboarding and the KYC processes. It only takes a very low to record all the mandatory information of humans from the documents using the AI systems.

    According to a report published by EY Insurance Industry Outlook 2021:

    • 69% of existing users want to buy insurance online.
    • 58% of users consider the online process of buying life insurance, and
    • 61% of users consider the online process of buying health insurance.

    AXA CZ/SK is one of the significant examples which uses deep learning models to improve the data ecosystems and efficiency and reduce the cost of human labour.


    Accurate Underwriting Risk Management

    In the insurance sector, underwriting stands for risk evaluation of insuring people or assets. When someone is applying for insurance, underwriters need to make different risk analysis strategies and policies precisely. These processes become very complex for a human to perform.

    As we know, AI models can be trained to perform more accurate decision-making when billions of data points are collected and fed to them. In addition, these systems can assess insurance applications against these training data points. They may also help the underwriters to get more clarity on relevant risk factors associated with a customer profile.

    Again a large amount of paperwork is required for underwriting that can be reduced using computer vision models with IoT devices. This way, we can record assets more carefully and faster or in real-time. This can also be utilised for eliminating in-person inspections over time.

    For example, by connecting a GIS data stream to analysis systems, we can enhance over-time inspection of properties while no in-person meetings are required. Also, we can adjust policies accordingly.

    All collected data can also be utilised in the following predictive analysis:

    • levels of degradation,
    • automatic defect inspections,
    • predict potential failure rates

    ICICI Lombard is one such application that helps in the cashless claims settlement process and insurance underwriting.


    Insurance Fraud Detection and Prevention

    According to a report on the official website of the united states government, the total cost of fraudulent activities in the insurance sector is more than $40 billion per year. And as we know, more than 7000 companies are serving insurance facilities in the USA. this amount of fraudulent activities can be compared to the plague.

    Looking at the figures one can estimate, it becomes necessary to apply such systems to the traditional techniques that can detect and prevent fraudulent activities. Nowadays, AI systems are developed to complete this necessity and augment human analysts’ judgement by providing them with highly optimised information.

    Since machine learning models can identify and optimise patterns from the information, they can be considered strong contenders for extracting out-of-the-ordinary behaviours.

    AI systems specially developed for fraud detection help in a quick and automatic background check of the customers either in the onboarding stages or in claim processing. They can also help estimate associated risk with any person or their assets.

    AXA is one of those examples of insurance companies that applied AI-enabled applications to prevent fraudulent activities. The applied software can detect distinct patterns based on computer behaviour and employee network.


    Customer Services

    Nowadays, AI has become one of the most valuable tools for representing a company’s competitive nature in the industry. Of course, that directly belongs to the marketing purposes, and for this also, AI can be utilised in any domain, not only in the insurance domain.

    Since the insurance domain is the top data holding domain, AI for customer services and marketing in the insurance domain can work better than in the other domain. AI is a crucial player in customer onboarding in the BFIS sectors. As AI has the power to optimise data, it can be used to predict more competitive prices or offers to enhance business models as per consumer demands.

    The only need to apply for the AI program here is to understand the trends with customers; for this, we may require to streamline the data collection and analysis on different channels. The outcome insights can be used for customer onboarding and product and policy designing.

    ZhongAn is a Chinese insurance company which utilises AI models and analytics to introduce innovative products and policies. For example, one of their policy insures against cracked mobile screens and shipping return products.


    Final words

    One thing which has been optimised in many reports is that COVID-19 has put this industry under pressure. AI has managed to hold the industry’s potential by improving operational efficiency, cost management and decision-making accuracy. Also, as the size of this industry is increasing, it won’t be surprising to see AI resolving many more use-cases of it. We have seen how this industry uses AI from enhancing operational efficiencies to increasing customer satisfaction.

  • The Power of Data Lineage: Types, Benefits and Implementation Techniques

    The Power of Data Lineage: Types, Benefits and Implementation Techniques

    Businesses heavily rely on accurate and reliable information to make critical decisions. However with data flowing from various sources and undergoing transformations, ensuring its quality can be a challenge. This is where data lineage comes in.


    What is Data Lineage?

    Data lineage can be thought of as the DNA of data. It’s a blueprint that illustrates the journey of data from its origin to its destination, detailing every transformation and interaction along the way. Data lineage can be called as a process of tracking the journey of data – from its origin to its final destination. It provides a clear picture of where the data comes from, what transformations it undergoes, and where it ends up. This includes:

    • Source: Identifying the initial source of the data, such as a customer relationship management (CRM) system, a sensor, or a social media platform.
    • Transformations: Tracking any changes made to the data during its journey, like filtering, aggregation, or calculations.
    • Destination: Understanding where the data is ultimately used, such as a data warehouse, an analytics application, or a reporting tool.

    Types of Data Lineage:

    Here are different types of data lineage:

    1. End-to-End Lineage: This provides a macro view, tracking data from inception to its final form. It covers every system and processes the data goes through, essential for compliance requirements and overall data governance.
    2. Source-to-Target Lineage: This focuses on documenting and understanding the journey of data from its source (origin) to its target (destination), including all transformations and processes

    Why is Data Lineage Important?

    Data lineage offers several benefits for organisations:

    • Improved Data Quality: By understanding the data’s flow, you can identify potential errors or inconsistencies at their source. This helps ensure the accuracy and reliability of your data analysis.
    • Efficient Troubleshooting: When issues arise in your data pipelines, data lineage allows you to quickly pinpoint the root cause, saving time and resources in debugging.
    • Enhanced Data Governance: Data lineage provides an audit trail for your data, making it easier to comply with regulations and data privacy requirements.
    • Effective Impact Analysis: When considering changes to your data pipelines, data lineage helps you understand the downstream impacts, minimising the risk of unintended consequences.

    How to Implement Data Lineage

    There are several ways to implement data lineage in your organization. Some of them are mentioned below:

    • Automated Tools: Data lineage tools can automatically capture and track data flows, providing a visual representation of the data journey.
    • Manual Documentation: While less efficient, data lineage can be documented manually through process flows and data dictionaries.
    • Data Catalogs: Centralized data catalogues can store information about data sources, transformations, and destinations, aiding in data lineage efforts.

    In today’s data-rich world, data lineage is no longer a luxury, but a necessity. Remember, data lineage isn’t just a technical concept; it’s essential for data quality, governance, and compliance. By understanding where data comes from and how it transforms, organisations can make informed decisions and ensure accurate data usage.

    Data lineage is a powerful tool for organisations that rely on data-driven decision-making. By understanding the flow of your data, you can ensure its quality, improve troubleshooting efficiency, and gain a deeper understanding of your data ecosystem.


    Seamless Data Lineage with UnifyAI – An Enterprise-Grade AI Platform

    Data lineage is a critical aspect of AI/ML workflows, ensuring transparency, traceability, and trustworthiness of data throughout its lifecycle. In UnifyAI, DSWs Enterprise Grade GenAI Platform, data lineage is meticulously managed and integrated into the platform, providing a clear and comprehensive view of the data’s journey from ingestion to deployment. This robust tracking mechanism is essential for compliance, auditing, and maintaining data integrity, especially in complex enterprise environments.

    DSW UnifyAI’s data lineage capabilities offer the following features:

    • End-to-End Traceability: Every dataset ingested into UnifyAI is meticulously tracked, recording its source, transformations, and final usage. This end-to-end traceability allows users to easily backtrack through each stage of the data’s lifecycle, ensuring that every modification and transformation is documented and can be reviewed.
    • Automated Documentation: The platform automatically documents all data transformations, feature engineering steps, and model training processes. This automated documentation is crucial for reproducibility, enabling teams to understand how specific results were achieved and to replicate or adjust workflows as needed.
    • Centralized Metadata Repository: UnifyAI includes a centralized metadata repository where all lineage information is stored. This repository acts as a single source of truth for data provenance, offering users quick access to detailed lineage records, which are essential for both internal audits and external regulatory compliance.
    • Interactive Lineage Visualization Graph: Users can leverage interactive visualization tools within UnifyAI to map out data lineage graphically. This intuitive interface helps in understanding complex data flows and dependencies at a glance, making it easier to manage and troubleshoot AI/ML pipelines.
    • Enhanced Collaboration and Consistency: By providing a transparent view of the entire data workflow, UnifyAI fosters collaboration among data scientists, engineers, and business stakeholders. Consistency in data usage and transformations across different projects and teams is maintained, reducing errors and ensuring that everyone is working with the same trusted data.
    • Compliance and Governance: UnifyAI’s lineage features are designed to support stringent compliance and governance requirements. Detailed lineage records ensure that all data usage complies with regulatory standards, and any discrepancies can be quickly identified and addressed. This is particularly important for industries with strict data governance mandates such as finance, healthcare, and government sectors.

    In essence, the integration of data lineage within UnifyAI ensures that organizations can confidently scale their AI initiatives, knowing that their data processes are transparent, traceable, and compliant. This not only enhances the reliability of AI models but also builds trust with stakeholders who can be assured of the integrity and accuracy of the data driving their insights and decisions.


    Want to build your AI-enabled use case seamlessly and faster with UnifyAI?

    Book a demo today!

    Authored by Yash Ghelani, MLOps Engineer at  Data Science Wizards (DSW), this article explores the pivotal role of data lineage in ensuring compliance, collaboration and trust and emphasizing the importance of understanding data transformation techniques and integrating accelerated transformations to streamline the AI journey for enhanced innovation and competitiveness


    About Data Science Wizards (DSW)

    Data Science Wizards (DSW) is a pioneering AI innovation company that is revolutionizing industries with its cutting-edge UnifyAI platform. Our mission is to empower enterprises by enabling them to build their AI-powered value chain use cases and seamlessly transition from experimentation to production with trust and scale.

    To learn more about DSW and our groundbreaking UnifyAI platform, visit our website at wordpress.datasciencewizards.ai/. Join us in shaping the future of AI and transforming industries through innovation, reliability, and scalability.
  • Streamlining Your Machine Learning Journey: The Ultimate Technologies Landscape for Efficiency and Scale

    Streamlining Your Machine Learning Journey: The Ultimate Technologies Landscape for Efficiency and Scale

    The fields of data science and artificial intelligence (AI) are rapidly evolving, with a dynamic array of technologies driving progress. From foundational algorithms to cutting-edge machine learning models, these tools are transforming how we analyze data and build intelligent systems. Lets understand a few prominent tools and technologies in this landscape.


    Landscape of Technologies

    1. Data Pipeline

    A data pipeline in any data science project is a set of processes and tools used to collect raw data from multiple sources, transform and clean it, and move data from various sources to its destination, often a machine learning model or a database. By automating these tasks, data pipelines streamline the data reparation phase, enabling data scientists to focus more on analysis and model building. Ultimately, data pipelines facilitate the extraction of valuable insights from raw data, powering informed decision-making. They enable companies to avoid the tedious and error-prone process of manual data collection and instead have constant access to clean, reliable, and up-to-date data that is essential for making data-driven decisions.

    • Apache NiFi

    Apache NiFi is an open-source data integration tool designed to automate the flow of data between systems. It provides a web-based interface for designing data flows, enabling users to drag and drop processors to create complex data pipelines. NiFi excels in real-time data ingestion, transformation, and routing, handling diverse data formats and sources. Its robust scheduling and backpressure mechanism ensure efficient data processing. In a data engineering pipeline, NiFi plays a critical role by streamlining data movement, ensuring data integrity, and facilitating seamless integration between various data sources and destinations, thereby enabling real-time analytics and operational intelligence. Its key features include guaranteed delivery, data buffering, prioritized queuing, and data provenance. NiFi is particularly useful for handling large volumes of data, ensuring scalability and reliability in the data engineering pipeline.

    • Estuary Flow

    “Estuary Flow” is a modern data engineering technology designed for orchestrating and automating data workflows. It enables the creation of scalable, fault-tolerant pipelines for ingesting, processing, and transforming data across various sources and destinations. With its intuitive interface and support for DAG (Directed Acyclic Graph) workflows, Estuary Flow streamlines data operations, ensuring efficient data movement and processing. Its role in a data engineering pipeline is pivotal, serving as a backbone for orchestrating tasks, managing dependencies, and monitoring workflow execution. Estuary Flow facilitates the seamless integration of disparate data sources, enabling organizations to derive actionable insights and drive data-driven decision-making processes.

    • PostgreSQL

    PostgreSQL, often referred to as Postgres, is an open-source relational database management system known for its robustness, extensibility, and adherence to SQL standards. In a data engineering pipeline, Postgres plays a fundamental role as a storage and processing engine. It efficiently stores structured data, offering powerful features for data manipulation, indexing, and querying. Data engineers leverage Postgres to persist and manage various types of data, from transactional records to analytical datasets. Its reliability and scalability make it a popular choice for data warehousing, operational databases, and serving as a backend for diverse applications within data ecosystems.

    • Feathr

    Feathr is an open-source feature store that focuses on providing a scalable solution for feature engineering and management. It enables efficient feature engineering and management in the data engineering pipeline. It provides a user-friendly interface for defining, computing, and serving features for machine learning models. Feathr abstracts the complexity of feature engineering, allowing data scientists to focus on building models rather than managing data pipelines. By centralizing feature definitions and computation, Feathr reduces engineering time and improves the performance of ML applications. It supports a wide range of data sources and can handle both batch and streaming feature computation.

    2. Modelling and Deployment

    Machine learning modeling involves training and validating models to solve specific problems. Deployment involves integrating these models into production environments where they can take in inputs and return outputs, making predictions available to others.

    • JupyterLab

    JupyterLab is an interactive development environment that facilitates data exploration, visualization, and prototyping of machine learning (ML) models. It offers a web-based interface for creating and sharing notebooks containing live code, equations, visualizations, and narrative text. In ML modeling, JupyterLab serves as a versatile workspace where data scientists can iteratively build, train, and evaluate models. JupyterLab interactive notebooks allow for immediate feedback, enabling practitioners to explore data, fine-tune algorithms, and communicate insights effectively, thus accelerating the development and deployment of ML solutions.

    • Ceph

    Ceph is an open-source, distributed storage platform that provides object, block, and file storage services. It employs a resilient architecture that ensures data redundancy and fault tolerance through replication and erasure coding. It is designed to be highly scalable, reliable, and self-managing, making it suitable for large-scale storage deployments. Ceph’s object storage system, known as RADOS (Reliable Autonomic Distributed Object Store), stores data as objects in a flat namespace. It uses the CRUSH algorithm to distribute data across the cluster, ensuring high performance and fault tolerance. The Ceph Object Storage Gateway (RGW) exposes the object storage layer through S3 and Swift-compatible APIs, allowing seamless integration with various applications and services. It ensures data availability and durability, supports seamless scalability, and integrates well with cloud-native environments.

    • Polyaxon

    Polyaxon is an open-source platform for managing, orchestrating, and scaling machine learning and deep learning experiments. It offers a user-friendly interface for data scientists, team leads, architects, and executives, providing features like tracking, orchestration, optimization, insights, model management, artifacts lineage, collaboration, management, compliance, and scalability. Polyaxon supports major deep learning frameworks and libraries, allowing seamless integration with various tools and frameworks for building, training, and monitoring machine learning models at scale. It integrates seamlessly with Kubernetes, enabling scalable and reproducible ML workflows. In the model development pipeline, Polyaxon plays a crucial role by allowing data scientists to efficiently run, monitor, and compare numerous experiments, automate workflows, and manage resource allocation. This facilitates collaboration, improves productivity, and ensures the reproducibility and scalability of machine learning projects.

    • Kubeflow

    Kubeflow is an open-source platform that simplifies the deployment and management of machine learning (ML) workflows on Kubernetes. In the model deployment process, Kubeflow plays a crucial role. It allows data scientists and ML engineers to package their models as Docker containers and deploy them to Kubernetes clusters. Kubeflow Pipelines, a key component, enables the creation of reusable and scalable ML workflows, facilitating the automation of model training, evaluation, and deployment. This helps organizations achieve consistent, reliable, and reproducible model deployment, while also enabling collaboration and monitoring throughout the ML lifecycle.

    3. ML Monitoring

    ML monitoring is the practice of continuously tracking the performance of machine learning models in production to identify potential issues, such as data drift, concept drift, and model fairness, and take corrective actions.

    • SigNoz

    SigNoz is an open-source observability platform designed for monitoring distributed systems, including machine learning models. It collects, analyzes, and visualizes metrics, traces, and logs in real-time to provide insights into system performance and behavior. SigNoz enables monitoring of model inference latency, error rates, and resource utilization, helping detect anomalies and performance degradation. It supports the tracing of requests across microservices, allowing for end-to-end visibility in model serving pipelines. In the model monitoring pipeline, SigNoz plays a crucial role by providing actionable insights into model performance, facilitating troubleshooting, optimization, and ensuring the reliability and effectiveness of machine learning applications.

    • Zabbix

    Zabbix is a comprehensive open-source monitoring solution that plays a crucial role in the Model Monitoring pipeline. It offers a wide range of features for monitoring the health, performance, and availability of models in production. Zabbix collects metrics from various sources, including models, and provides advanced visualization capabilities through customizable dashboards. It supports complex event processing, allowing users to define rules for detecting anomalies and triggering alerts. Zabbix’s scalability and flexibility make it suitable for monitoring models in large-scale environments, ensuring reliable and efficient model deployment and operation.

    • Fiddler AI

    Fiddler AI is an open-source AI observability platform that plays a crucial role in the Model Monitoring pipeline. It provides a comprehensive solution for monitoring, analyzing, and explaining machine learning models in production. Fiddler AI offers features like data drift detection, data integrity checks, outlier identification, and real-time alerting to help teams catch issues early. It supports a wide range of models, including natural language processing and computer vision, and integrates with popular ML frameworks. By providing actionable insights and enabling collaboration, Fiddler AI helps organizations deliver high-performing, responsible AI applications faster. It plays a crucial role by enabling organizations to continuously monitor and optimize their machine learning models, ensuring they remain accurate, fair, and reliable throughout their lifecycle, thereby enhancing trust and mitigating risks.


    Streamlining the entire landscape with DSW UnifyAI – Enterprise GenAI platform

    The primary objective of the DSW UnifyAI platform is to establish a centralized machine learning platform that harnesses multiple technologies to streamline and simplify the process of building, experimenting, deploying and managing machine learning models into production. By abstracting away the complexities inherent in model deployment, DSW UnifyAI aims to accelerate and smooth the transition from model development to operational deployment. The platform facilitates several key functions, including but not limited to:

    Centralization: DSW UnifyAI consolidates various aspects of the machine learning lifecycle, including data preparation, model training, evaluation, and deployment, into a single, cohesive platform.

    2. Integration of Technologies: It seamlessly integrates multiple technologies and tools required for different stages of the machine learning pipeline, ensuring interoperability and efficiency.

    3. Abstraction of Complexities: DSW UnifyAI abstracts away the intricate details and technical challenges involved in model productionisation, allowing data scientists and engineers to focus on model development and business insights rather than deployment complexities.

    4. Swift Productionisation: By abstracting heavy complexities, DSW UnifyAI enables rapid and efficient deployment of machine learning models into production environments, reducing time-to-market and accelerating the realization of business value from AI initiatives.

    5. Seamless Workflow: It facilitates a smooth workflow from model development to deployment, providing tools and features to streamline collaboration, version control, testing, and monitoring of deployed models.

    6. Scalability and Flexibility: DSW UnifyAI is designed to scale with the organization’s needs, supporting the deployment of models across diverse environments, from cloud to on-premises infrastructure, and accommodating various deployment scenarios.

    Overall, the DSW UnifyAI platform serves as a comprehensive solution for organizations seeking to leverage machine learning effectively, offering the tools and technologies needed to operationalize models efficiently and effectively. The platform facilitates the following features for building end to end AI use cases:

    1. Data Ingestion toolkit to acquire data from varied source systems and persists in the DSW UnifyAI for building use cases.
    2. Feature Store for feature engineering, feature configuration to serve features during model development/inference.
    3. Model Integration and Development for the data scientist/user to experiment, train AI models, and store the experiment results in the model registry. Followed by choosing a candidate model for registration along with versioning capability through metrics comparison.
    4. AI Studio to facilitate the automatic creation of baseline use cases and boilerplate code in a matter of few clicks.
    5. GenAI to help generate quick data insights through conversational interaction on user-uploaded data.
    6. Model Repository to enable Data scientists/users to manage and evaluate model experiments.
    7. One-click model deployment through the UnifyAI user interface.
    8. A user-friendly user interface to evaluate and monitor model performance.

    Want to build your AI-enabled use case seamlessly and faster with DSW UnifyAI?

    Book a demo today!

    Authored by Hardik Raja, Senior Data Scientist at Data Science Wizards (DSW), this article delves into the realm of various technologies in data science and machine learning projects, covering the entire landscape from data engineering to model deployment to model monitoring. It also showcases how this entire process of machine learning project lifecycle can be streamlined through the DSW UnifyAI platform. Using it, enterprises can accelerate the development cum deployment of machine learning solutions, paving the way for enhanced efficiency, robustness, acceleration and competitiveness.


    About Data Science Wizards (DSW)

    Data Science Wizards (DSW) is a pioneering AI innovation company that is revolutionizing industries with its cutting-edge UnifyAI platform. Our mission is to empower enterprises by enabling them to build their AI-powered value chain use cases and seamlessly transition from experimentation to production with trust and scale.

    To learn more about DSW and our ground-breaking UnifyAI platform, visit our website at www.datasciencewizards.ai/. Join us in shaping the future of AI and transforming industries through innovation, reliability, and scalability.

  • Unlocking Data Potential: The Power of Data Transformation in AI Use Cases

    Unlocking Data Potential: The Power of Data Transformation in AI Use Cases

    When applying data science, machine learning and artificial intelligence to different use cases, one should always take care of one fact raw data is difficult to understand and trace. Here, the need for data processing comes in forward so that critical, accurate and valuable information can be retrieved. Data transformation is one of the techniques that we use in between data processing. This technique lets us convert the raw data into a required format so that the next procedures of data processing and data modelling can be performed efficiently.

    Technically, data transformation changes the data structure, format and value and makes it clean and usable for the next processes. There can be two stages of data transformation processes because many organisations use data warehouses arranged in the ETL process, where data transformation is an in-between process. On the other hand, nowadays, many organisations rely on cloud-based data warehouses, which makes them capable of loading raw data and transforming the data in query time.

    Data transformation entails altering the structure, format, and values of data to render it clean and usable for further processes. This process is integral across the entire data processing pipeline, from data integration to the final stages of data wrangling. Typically, there are several types of data transformation:

    1. Constructive: Involves adding, copying, or replicating data.
    2. Destructive: Entails deleting records or fields.
    3. Aesthetic: Focuses on standardizing data to enhance its value.
    4. Structural: Involves reorganizing data by moving, merging, or renaming columns.

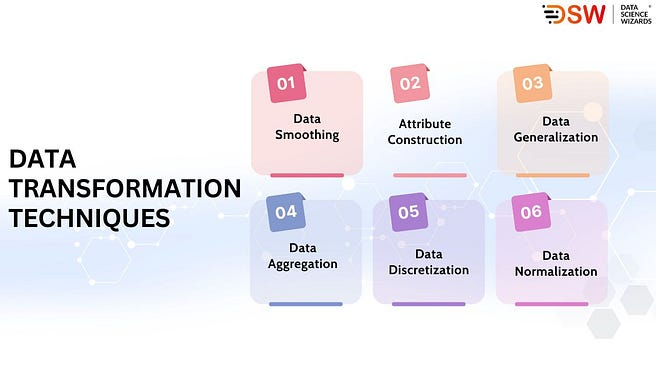
    Now let’s delve into various general data transformation techniques:

    unlocking-data-potential2

    1. Data Smoothing: This technique aims to remove noise from data, potentially employing algorithms to enhance the visibility of important data features and facilitate pattern prediction. Analysts often employ techniques like binning, regression, and clustering to achieve noise reduction.
    2. Attribute Construction: Here, new attributes are added to the data based on existing attributes, simplifying data ingestion processes and elucidating relationships among attributes. For instance, combining height, width, and length attributes to derive a volume attribute can streamline data interpretation.
    3. Data Aggregation: This technique summarizes data from various sources into a condensed form, crucial for generating comprehensive reports such as annual sales reports based on quarterly or monthly data.
    4. Data Normalization: Involves scaling data within a smaller range (e.g., between 0 to 1 or -1 to 1) to eliminate redundancy, enhance consistency and accuracy, and facilitate easier data maintenance. Techniques like Min-Max normalization and Z-score normalization are commonly employed.
    5. Data Discretization: This process converts continuous data into intervals, improving interpretability and facilitating analysis. It simplifies data by transforming continuous values into categorical attributes, categorized into supervised and unsupervised discretization methods.
    6. Data Generalization: Relies on hierarchy to transform low-level data attributes into high-level ones, offering a clearer picture of the data. It can be achieved through approaches like the data cube process (OLAP) or attribute-oriented induction (AOI).

    Now, let’s explore the data transformation process:


    Data Transformation Process:

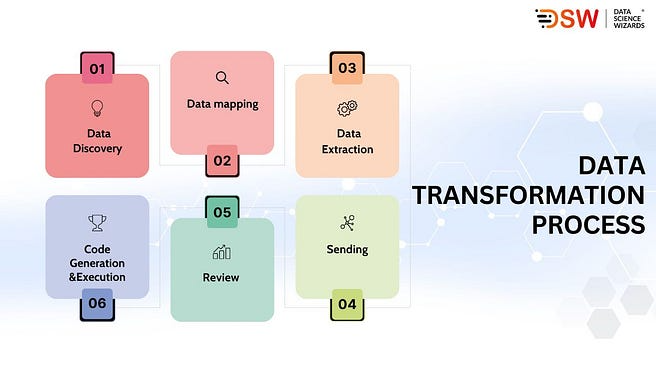
    The data transformation process typically falls under the ETL (Extract, Transform, Load) paradigm:

    unlocking-data-potential3

    1. Data Discovery: Understanding the data source using profiling tools to determine the necessary transformations.
    2. Data Mapping: Defining how fields are mapped, modified, filtered, joined, or aggregated.
    3. Data Extraction: Extracting data from its original sources, such as databases or log files.
    4. Code Execution: Generating and executing code to transform data into the required format.
    5. Review: Ensuring the accuracy of data transformation.
    6. Sending: Transmitting transformed data to its target destination, such as a relational database or warehouse.

    These processes can be categorized into three general ways:

    1. By Scripting: Writing codes in languages like Python or SQL to query and transform data, offering automation and reduced coding requirements.
    2. Using ETL Tools: Employing tools designed to simplify data extraction and transformation, often requiring expertise and infrastructure.
    3. Cloud-Based ETL Tools: Utilizing cloud-hosted tools for easy data extraction, transformation, and loading, offering accessibility and scalability even to non-technical users.

    Advantages of Data Transformation:

    unlocking-data-potential4

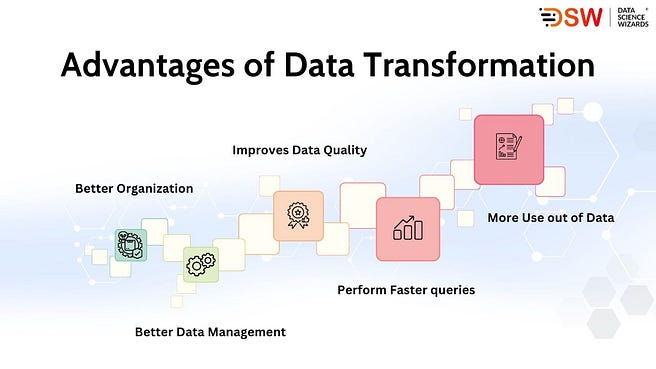
    • Enhanced data quality, leading to reduced risks and costs associated with low-quality data.
    • Accelerated query processing for quick access to transformed data.
    • Efficient data management through refined metadata.
    • Improved organization and interpretability of data for both humans and computers.
    • Maximization of data utilization by standardizing and enhancing usability.

    In conclusion, data transformation is an indispensable process for organizations seeking to unlock the full potential of their data. By employing various techniques and processes, businesses can derive valuable insights, streamline operations, and drive informed decision-making.


    DSW UnifyAI – An Enterprise GenAI Platform

    DSW UnifyAI stands as a comprehensive Enterprise-grade GenAI platform, seamlessly integrating all essential components for flawless AI/ML implementation. By eliminating fragmented tools and expediting processes, UnifyAI offers a unified and cohesive environment for end-to-end AI/ML development, spanning from experimentation to production. Rooted in acceleration, UnifyAI drastically diminishes the time, cost, and effort needed for experimenting, constructing, and deploying AI models, facilitating organizations to effectively scale their AI initiatives across the enterprise.

    DSW UnifyAI boasts advanced feature transformation capabilities that streamline the entire data preprocessing pipeline, spanning from data ingestion to feature storage. Its robust data ingestion toolkit effortlessly manages diverse datasets, while a comprehensive library of transformation functions and algorithms efficiently preprocesses data within the platform. Features undergo automatic extraction, transformation, and storage in the centralized Feature Store, fostering consistency and collaboration across projects and teams.

    Moreover, UnifyAI’s AI Studio further expedites the data and feature engineering process by autonomously selecting and applying optimal transformations based on the given model type. This integration of advanced data engineering capabilities directly within the platform empowers users to derive actionable insights more efficiently, fostering innovation and gaining competitive advantage from their data.


    Want to build your AI-enabled use case seamlessly and faster with UnifyAI?

    Book a demo today!

    Authored by Sandhya Oza, Co-founder and Chief Project Officer at  Data Science Wizards (DSW), this article explores the pivotal role of data transformation in optimizing machine learning models, emphasizing the importance of understanding data transformation techniques and integrating accelerated transformations to streamline the AI journey for enhanced innovation and competitiveness.


    About Data Science Wizards (DSW)

    Data Science Wizards (DSW) is a pioneering AI innovation company that is revolutionizing industries with its cutting-edge UnifyAI platform. Our mission is to empower enterprises by enabling them to build their AI-powered value chain use cases and seamlessly transition from experimentation to production with trust and scale.

    To learn more about DSW and our groundbreaking UnifyAI platform, visit our website at www.datasciencewizards.ai/. Join us in shaping the future of AI and transforming industries through innovation, reliability, and scalability.